Finding perfect note taking and task listing tools

{{This article was originally posted on December 29,2016. Lost and found, here it is reposted.}}

Update 2: last year I had downloaded an app called Mynotex and not bothered to try it. The 30th and 31st of December, 2016 saw me testing it after I noticed it in my Downloads folder. 1st Jan, 2017 — I have switched to a new note taking application and it is Mynotex. Simple to earn, easy to use and it fulfills most criteria I had including easy import/export, migration. Saves data in sqlite format, so I can access with Python. Main point though is how is arranges all by notes using Subjects and titles.

Update 1 : a new app that I just saw is called Remember (https://github.com/sanchitgn/remember). It seems to be good, but for me it is web based. So not going for it.

I have this obsession of trying to find the perfect tool for note taking and task listing tools. So every once in a while (mainly when I upgrade my OS) I go on a binge to look for solutions that are out there and try them for their look and feel. I have tried just about every open source or free tool that is out there, that can run on Linux and sometimes with wine over Linux.

Even when I write this there seems to be a new tool out there that was directed through this post on Medium https://medium.com/@mobitar/evernote-is-what-happens-when-you-mix-vc-with-a-notes-app-8a6a9ce5a9c5#.x8cvjl29z called Standard Notes (https://standardnotes.org/) that I am downloading to check it out. I liked what is written on the Standard Notes site — A standard notes app with an un-standard focus on longevity, portability, and privacy. Journey through it and with it is yet to begin though.

I am coming to a point where I am going to upgrade my OS. So just recaping all the tools that I tried for note taking and task listing tasks.

I started off with Tomboy Notes as it came standard with the Linux Mint install. Quickly I switched to Sticky Notes that came with Linux as a Panel App. Tomboy was taking too long to load. So that slowness when it came up really disappointed me. Sticky Notes is fast, but it is notes. So use it to put in important things only. I wanted to compartmentalize notes and wanted something to work as todo also. Sticky notes did not have the features.

Then I thought I might be trying to mix 2 separate requirements into one. So it might be better to look for separate solutions for notes and task lists.

First for the task list : though there were a lot of good solutions for Android devices, I could not find them working well on Linux or vice versa. I separated the two with the thought that i did most of my tasks on Linux and would prefer a good solution for it. Two solutions quickly came up : todo.txt and taskwarrior, both for the command line. But I had to either keep a terminal open at anytime or jump to one again and again. Being as lazy as I am that was too much of a task. So looked around for GUI addons for them, found Ptask for taskwarrior and QTodoTxt for todo.txt I found a lot more, but most did not make through my pickyness of either being written in Python or native to GNOME or QT. Many I found were in JAVA, somehow I tend to find applications written in JAVA a little too quirky for my needs, so tend to avoid anything and everything written in JAVA. I have not been able to decided which among the two and not really using both as the issue of if I create todo list in one how do I get them in the other. Hehe…

On the Notes side I am happily settled with NVPY, though it is not all that I was looking for. It seems I like NVPY mainly for what it is — a rather ugly but cross-platform simplenote client. To be fair to NVPY its minimalist view, simplicity and good search is what I like the most.

But there are many more that either I have started something or installed and not used and then there are the ones that I just gave up on reading about them.

One of the first apps I tried was Xournal. I found to be a little bit off my taste mainly due to the mouse based writing feature. I guess it might be a lot better if I could use a pen like device or maybe on a tablet. Xournal reminds me too much of my Palm Pilot m105 digital assistant device. The device had a really small input screen where with a scribe one could draw patterns and that would turn into letters. I never got the hang of it and found it pretty painful. Incidentally that was also the first device on which I tried to make a survey data collection tool. Neither my data collection tool nor the palm pilot went a long way. So that was the end of it.

Rednotebook had just too many things to look at. My brain never got around the options and calender based navigation. What if I wrote notes based on topics and really didn’t stick to dates? It felt more like a dairy.

Springseed was too slow and then its working mechanism was a little too much. I guess since it was just in beta release I should not have expected much.

There were Zim Desktop Wiki, Keepnote and Gnote. Too complex, too laborous and just too simple. Hehe… There was Everpad that worked with Evernote.

One though I did find good and used for a while is Basket Notes. That was good, but the hierarchical structure started getting to me.

All along I kept going back and forth with NVPY. Finally just continued with it.

Note : Sadly the Standard Notes, that I mentioned above, just refused to start on my Linux Mint 17.3 machine. So giving up on it too

Bucket List

{{This article was originally posted on December 22, 2016. My posts were lost and after being found I am re-posting them.}}

One day (in 2011) got a whim to try and write a Python program to that will try and find the best combinations of numbers (within given range and given tolerances) that will add up to a fixed target total. Didn’t think of much use for it then, but have used it in multiple instances to get some good results. The algorithm works as the diagram below :

The Python code for it :

import random
def generateBucketList():
    fixedTargetTotal = 94
    bucketMidPoints = [[10, 5], [5, 10], [6], [5], [5], [6], [6], [8], [6], [8], [5, 5, 5, 5]]
    bucketAssign = [1, 2, 3]
    rangeFromMidPoint = [2, 2, 1, 1, 1, 1, 1, 1, 1, 1, 4]
    bucketMidPoints = sum(bucketMidPoints, [])
    finalAssign = []
    if sum(bucketMidPoints) > fixedTargetTotal:  # reduce(lambda x, y: x + y, bucketMidPoints) > fixedTargetTotal:
        while sum(bucketAssign) != fixedTargetTotal:  # reduce(lambda x, y: x + y, bucketAssign) != fixedTargetTotal:
            # bucketAssign = [random.randint(int(0.6*i),i) for i in bucketMidPoints]
            bucketAssign = []
            for i in bucketMidPoints:
                if i != 0:
                    bucketAssign.append(random.randint(int(0.6 * i), i))
                else:
                    bucketAssign.append(i)
    else:
        marks = "Bucket dispersal is not above given expected Target Total"
    # Print the list in given order from here
    startMarker = 0
    endMarker = 0
    for i in rangeFromMidPoint:
        endMarker = endMarker + i
        tempList = bucketAssign[startMarker: endMarker]
        finalAssign.append(tempList)
        startMarker = startMarker + i
    for i, j in enumerate(finalAssign):
        print i + 1, " -> ", j
    print "\n"
    print bucketAssign, sum(bucketAssign)  # reduce(lambda x, y: x + y, bucketAssign)

if __name__ == "__main__":
    generateBucketList()
    print "Demo!!!..."

Weather Predictor — in Python

{{This article was originally posted on December 22, 2016. My posts were lost and after being found I am re-posting them.}}

“””This is based on my binge study to learn about climate change and predicting weather at rural community levels using low power devices. Original thought was to try and do community level weather predicting so that locals are aware of the changes that are occuring around them and plan for agriculture better.“”” Hearing much about climate change and weather pattern changes got me thinking if I could make a simple weather prediction system. For hardware I had a raspberry pi that had temperature sensor, humidity sensor and pressure sensor. Then I didn’t have rain guage or wind direction sensor, but I wanted to suppose that if I had all that, could I use the raspberry pi to predict weather parameters at local level. My thought if I could have a lot of cheap weather monitoring stations at community schools in villages, then I could use my system to predict the weather at the station as well as pass on the data to other stations. So other stations could predict using their data and the one sent from the first one. slowly the data would be passed to each other resulting in more accurate predictions. Without bothering about how to pass the data I looked at ways of creating a simple wether prediction system that could easily work off raspberry pi as well as be able to scale up to parallelly be able to predict these parameters when used at aggregator levels. I settled on the windowing technique to do the prediction as described on the paper : http://www.hindawi.com/journals/isrn/2013/156540/ Weather data is available through a CSV file in following format:

datemaxTempminTemprainfallmorningHumidityeveningHumidity
2004-01-0118.82.4096.981.7
2004-01-02191.1096.978.5
2004-01-0318.31.7010086.6
2004-01-0418.31096.782.6
2004-01-0517.81.3096.786.9
2004-01-0619.52094.465.7
2004-01-0720.9209772.5

Explanations : The way the algorithm is implemented right now is as follows: from the latest 7 days weather parameter data a 7 day dataframe is created this dataframe is compared against a running window of 7 days dataframe going through the whole year and then over years. the dataframe and testframe that creates the least delta is taken as similar weather predictions. The delta is added to dataframe and predictions given. My list of readings is below :Books :

  • DETECTING TREND AND OTHER CHANGES IN HYDROLOGICAL DATA Zbigniew W. Kundzewicz and Alice Robson (Editors) WMO/TD-No. 1013 (Geneva, May 2000)
  • Weather and Climate Extremes in a Changing Climate Regions of Focus: North America, Hawaii, Caribbean, and U.S. Pacific Islands U.S. Climate Change Science Program
  • Synthesis and Assessment Product 3.3 June 2008
  • Introduction to Time Series Analysis and Forecasting DOUGLAS C. MONTGOMERY, CHERYL L. JENNINGS, MURAT KULAHCI Wiley Publications 2008
  • An Introductory Study on Time Series Modeling and Forecasting Ratnadip Adhikari R. K. Agrawal
  • Python In Hydrology Sat Kumar Tomer Green Tea Press 2011

Articles :

  • Trend analysis of rainfall and temperature data for India Sharad K. Jain and Vijay Kumar
  • Detecting changes in rainfall pattern and seasonality index vis-`a-vis increasing water scarcity in Maharashtra Pulak Guhathakurta and Elizabeth Saji
  • Trend Detection in the Temporal Pattern of the Precipitation at Different Timescales – Application to a Case Study: the Watershed of the Stream Gauging Station of Torrão Do Alentejo. Ana RAMALHEIRA, Maria Manuela PORTELA, Cristina FAEL
  • Correlation and Regression without Sums of Squares (Kendall’s Tau) Rudy A. Gideon
  • Change detection in hydrological records—a review of the methodology / Revue méthodologique de la détection de changements dans les chroniques hydrologiques Zbigniew W. Kundzewicz & Alice J. Robson
  • Changes in the intra-annual rainfall pattern as an evidence of climate change Carlos Manuel Cotafo Martins
  • Application of Data Mining Techniques in Weather Prediction and Climate Change Studies Folorunsho Olaiya

github repo : https://github.com/pravenj/weatherPredict

Jump Search

{{This article was originally posted on December 22, 2016. My posts were lost and after being found I am re-posting them.}}

Few years ago (I think in 2013), I read this article on Jump Search : http://www.stoimen.com/blog/2011/12/12/computer-algorithms-jump-search/ Since the code presented was in php, got the urge to try it in Python. So wrote the code, forgot about it and discovered it in my hard drive few months ago. So putting it up as an archive. The Jump Search works as in picture below:

Fig.: diagrammatic representation of how jump search works

My Python code is as given below:

import math

def jumpSearch(noToSearch, lis):
    lenOfList = len(lis)
    prev = 0
    counter = 0
    step = int(math.floor(math.sqrt(lenOfList)))
    while lis[step if step < lenOfList else (lenOfList-1)] < noToSearch:
        prev = step
        print "Inside while : ", prev
        step = step + int(math.floor(math.sqrt(lenOfList)))
        counter = counter + 1
        print "Count : ", counter
        if step >= lenOfList:
            break
    while lis[prev] < noToSearch:
        prev = prev + 1
        counter = counter + 1
        print "Count : ", counter
    return prev+1

if __name__ == "__main__":
    lis = range(1,1000)
    print jumpSearch(624, lis)

Image Calendar Generator

Note : This project was done in 2007. So some of the code needs to be explored to explain.

I wanted to take images like below:

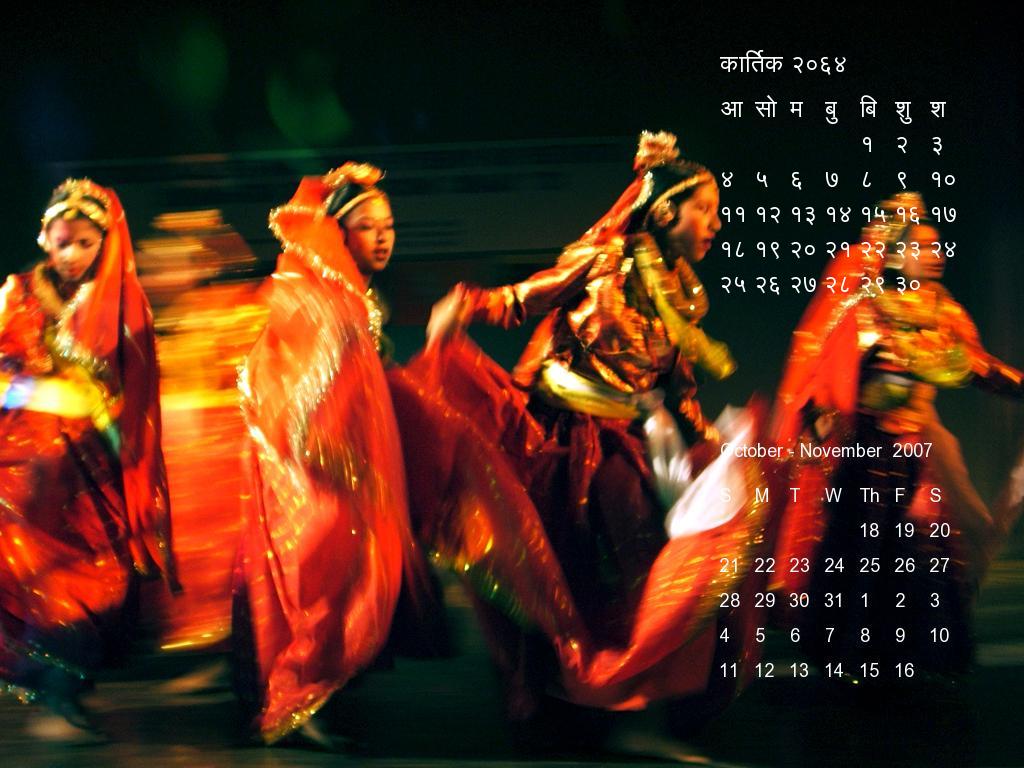
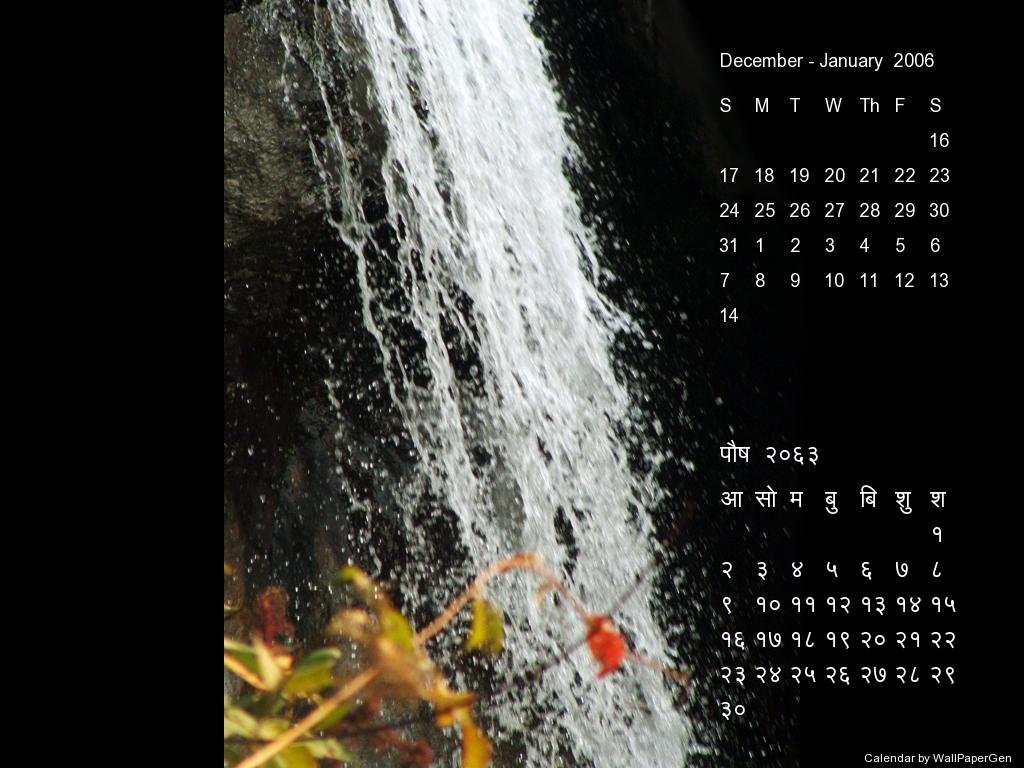
And add Nepali and English calendars to them like below so that I could use them as my wallpaper as well as a calendar — Something like a desk calendar.

I created a Python app to do this and below is how the setup screen looks.

The application can be started from the command-line like below :

>>python wallPapergen.py

Once all parameters are setup in the setup screen I could generate the calendars on top of images using the famed Python PIL (Python Imaging Library) library.

Setup screen for the Calendar on Image generator

There is a quick help as to what each of these parameters are on the top right corner shown with a question mark icon.

Few parameters worth talking about it are:

Colors : we can select among a variety of colors. I think the idea was to choose colors that standout the most in the images for the calendar/s to be visible.

Direction : total of 9 directions are available to place the calendar on images. These 9 directions are all around the corners and one at the center.

Date Format : this is the confusing one. I don’t even remember why I put it there. What it does is either generate the Nepali calendar first and generate English calendar based on the Nepali calendar or vice versa.

Other options are pretty self-explanatory.

The three core files to this code are:

createCalendarPicture.py : this contains the core methods that take the picture, get calendar data from dateConverter.py and put the calendar as image onto the picture

dateConverter.py : does the date conversion between Nepali dates and English dates

dateData.py : this is the Nepali Calendar database with Year and days of the month. Nepali months can have anywhere between 28 to 32 days.

Note : This code was designed for a 1024×768 screen size.

Full code for the Wall Paper Calendar generator — http://www.prjoshi.com/wp-content/uploads/2020/01/calendar_code.zip

The Marks Distributor

Note : You really don’t want to use this software. It is a system designed for research purposes and looking at working of codes for automated data generation.

While teaching some subjects at the Master’s level, I realized that most often marks are not exactly what determines the students. In this case the marks were just arbitrary numbers we assigned to exams based on their everyday performance as well as their experiences relative to the field of study.

So I got the urge to write a program that would arbitrarily assign marks to questions then adds all that up to get to a pre-determined total. This program was created over a day of not finding anything to do and wanting to test out how believable enough a random marks assigner would be.

Let me start with the result (output) of the code that will given a little later and talk about the result.

1 -> [10, 5]
2 -> [5, 10]
3 -> [3]
4 -> [5]
5 -> [5]
6 -> [5]
7 -> [5]
8 -> [8]
9 -> [6]
10 -> [7]
11 -> [5, 5, 5, 5]

[10, 5, 5, 10, 3, 5, 5, 5, 5, 8, 6, 7, 5, 5, 5, 5] 94

From the above, it states that Question 1 had 2 sub-questions, 1 of 10 marks and other of 5 marks. If one looks at question 11, then there are 4 sub-questions of 5 marks each.

The paper is supposed to be marked for a total of 94. [10, 5, 5, 10, 3, 5, 5, 5, 5, 8, 6, 7, 5, 5, 5, 5] is the marks assignment that the software comes up with to get to the 94.

Below is code in its entirety. All code was written in Python 2.7 on Linux Mint.

import random

def generateMarksList():
    givenFullMarks = 94
    marksDispersal = [[10, 5], [5, 10], [6], [5], [5], [6], [6], [8], [6], [8], [5, 5, 5, 5]]
    marksAssign = [1, 2, 3]
    marksBlock = [2, 2, 1, 1, 1, 1, 1, 1, 1, 1, 4]
    marksDispersal = sum(marksDispersal, [])
    finalAssign = []
    if sum(marksDispersal) > givenFullMarks: 
        while sum(marksAssign) != givenFullMarks:
            marksAssign = []
            for i in marksDispersal:
                if i != 0:
                    marksAssign.append(random.randint(int(0.6 * i), i))
                else:
                    marksAssign.append(i)
    else:
        marks = "Marks dispersal is not above given full marks"
    startMarker = 0
    endMarker = 0
    for i in marksBlock:
        endMarker = endMarker + i
        tempList = marksAssign[startMarker: endMarker]
        finalAssign.append(tempList)
        startMarker = startMarker + i
    for i, j in enumerate(finalAssign):
        print i + 1, " -> ", j
    print "\n"
    print marksAssign, sum(marksAssign)

if __name__ == "__main__":
    generateMarksList()
    print "Demo!!!..."

The magic in this code happens in the generateMarksList function. Here marks are calculated per question and assigned to a finalAssign variable to get a total of the total marks assigned. This is a bruteforce method where marks start to go upwards from 0 to get to a value that will get the total to given one.

Each mark assigned is allowed to have some leeway in how the marks are assigned to not give full marks to questions if and when possible.

I later used this marks generator to create datasets for my student cluster generator, that has been posted as a blog here — http://www.prjoshi.com/?p=11

Nepali Units Converter

Python scripts that allow for conversion among legacy based local Nepali units of area, volume and weight to metric units and among themselves and vice versa.

The formulas used if obtained from Nepal Rastra Bank, Agriculture Survey Report, 1972 where the formula is given comprehensively.

These set of scripts are created as an archive of the formula as no other comprehensive conversion script seem available.

These formulas have been used in agriculture related applications.

How it is arranged :

  • formulas.py — all weights that are required for conversion
  • areaConverter.py — formulas for area conversion
  • volumeConverter.py — formulas for volume conversion
  • weightConverter.py — formulas for weight conversion

The scripts to use the formulas :

  • nepaliUnitConverter.py — commandline script to convert
  • converter.py — a basic wx based gui for conversions

Usage :

One can either edit the nepaliUnitConverter.py file, make necessary changes to the following code at the bottom of the file:
localUnit = “MuriMato”
metricUnit = “Hectares”
valueToBeConverted = 1
fromTo = “Metric To Local” #can be Metric to Local, Local to Metric
currentUnits = “area” #can be Area, Weight or Volume
and run the script

or

one can run the GUI and do the conversions there

The formulas and the conversions that have been inplemented are below:

multiplying factors

Area measurements

Local area to metric area

muriMatoToHectares = 0.0127
pathiMatoToHectares = 0.0006
ropaniToHectares = 0.0509
bighaToHectares = 0.6800
annaToHectares = 0.0032
dhurToHectares = 0.0017
kathaToHectares = 0.0338

to smaller units in local area

muriMatoToPathiMato = 20
pathiMatoToManaMato = 8
ropaniToAnna = 16
bighaToKatha = 20
kathaToDhur = 20

Weight and volume measurements

Local Weights to metric Weights

maundToKilograms = 37.3240
dharniToKilograms = 2.3325
sheerToKilograms = 0.9331
pausToKilograms = 0.1944

to smaller weights in local weights

maundToSheers = 40
dharniToPaus = 12

Local volume to metric Weights

muriPaddyToKilograms = 50.00
muriWheatToKilograms = 67.30
muriMaizeToKilograms = 62.70
muriMilletToKilograms = 67.30

pathiPaddyToKilograms = 2.5000
pathiMaizeToKilograms = 3.1350
pathiWheatToKilgrams = 3.3650
pathiMilletToKilograms = 3.3650

to smaller volume in local volumes

muriToPathi = 20
pathiToMana = 8

DISCLAIMER

I have not put too much effort into this to be used as a working application, rather worked on it on the part of preserving the formulas and the weights as well as to provide a simple documentation of local units used for area, weight and volume. So the application itself is rusty for use.

Download Python Script here — http://www.prjoshi.com/wp-content/uploads/2019/12/NepaliUnitConverter.zip

Small Data Analysis using Exam data

Trying to analyze marks obtained by students in exams and getting something meaningful out of it has been something that I had planned on working for a long time.

The reason for not jumping in was mainly around what tools I would use to do the analysis. Though conventional statistics could provide most of what I was looking to, I wanted to go a little further and look into ways of categorizing students to find topics that should be repeated to them.

Having gone though a bit of Decision trees and K Means clustering I decided to use these and see how they work in small datasets. *A sample dataset is added at the end of the article.

The dataset is for a particular exam paper (this being Physics). It consists of marks obtained by students in each of the questions, the total and a grade that is given for a range of totals.

To make it simple for analysis I normalized the scores to 0 and 1. This had to be done as the highest score for individual questions varied.

First off I created a box and whisker plot of the marks.

Block and Whisker plot for student data

This should variation in marks for Q4, Q8 are very wide while those for Q0, Q5, A13 and Q14 are narrow — meaning students scored near each other for Q0, Q5, A13 and Q14.

To find out questions that really changed the scores for the students, I created a decision tree.

Decision tree for the marks analysis

This Decision tree gives the questions that groups of students either scored high in or scored low in. If we follow the tree along the left most path, one finds that many students (12 out of 34) have done badly in question number 7. Also ones who have done well in questions Q7 have also done well in question 5. At the top of the tree the students who have not done well in Q6, seem have not done well in most of the questions.

Having learned this I set out to build a K mean cluster to see the students group based on the marks they scored. Below is the cluster visualization.

The cluster with the red dots show students that are faring along well compared to others in all questions. The ones in yellow are not faring along well and need attention in all questions. If one goes back to the Decision tree the yellow dot group did really badly in Q6, Q1 and Q7 thereby moving towards the left end of the K means cluster.

This is starting of data analysis tool for students data. The thought behind this is that in Nepal and countries around it, large scale exams will happen and we need to find ways to analyze this data to provide education opportunity to students based on how they are faring in them.

Zip file of code and sample data — http://www.prjoshi.com/wp-content/uploads/2019/12/BVS_marksAnalyzer.zip